12 Haziran 2023 Pazartesi

Supervisory Control and Data Acquisition - SCADA

Giriş
ındustrial IoT ve Industry 4.0 ile daha da önemli hale geldi. Şeklen şöyle

Gelişimi şöyle
First generation: Monolithic
Second generation: Distributed
Third generation: Networked
Fourth generation: Web-based
Fifth generation: Cloud-native and open SCADA systems.


9 Haziran 2023 Cuma

Quotient Filter - Probabilistic Data Structure - False Positive Bulunur

Giriş
Açıklaması şöyle
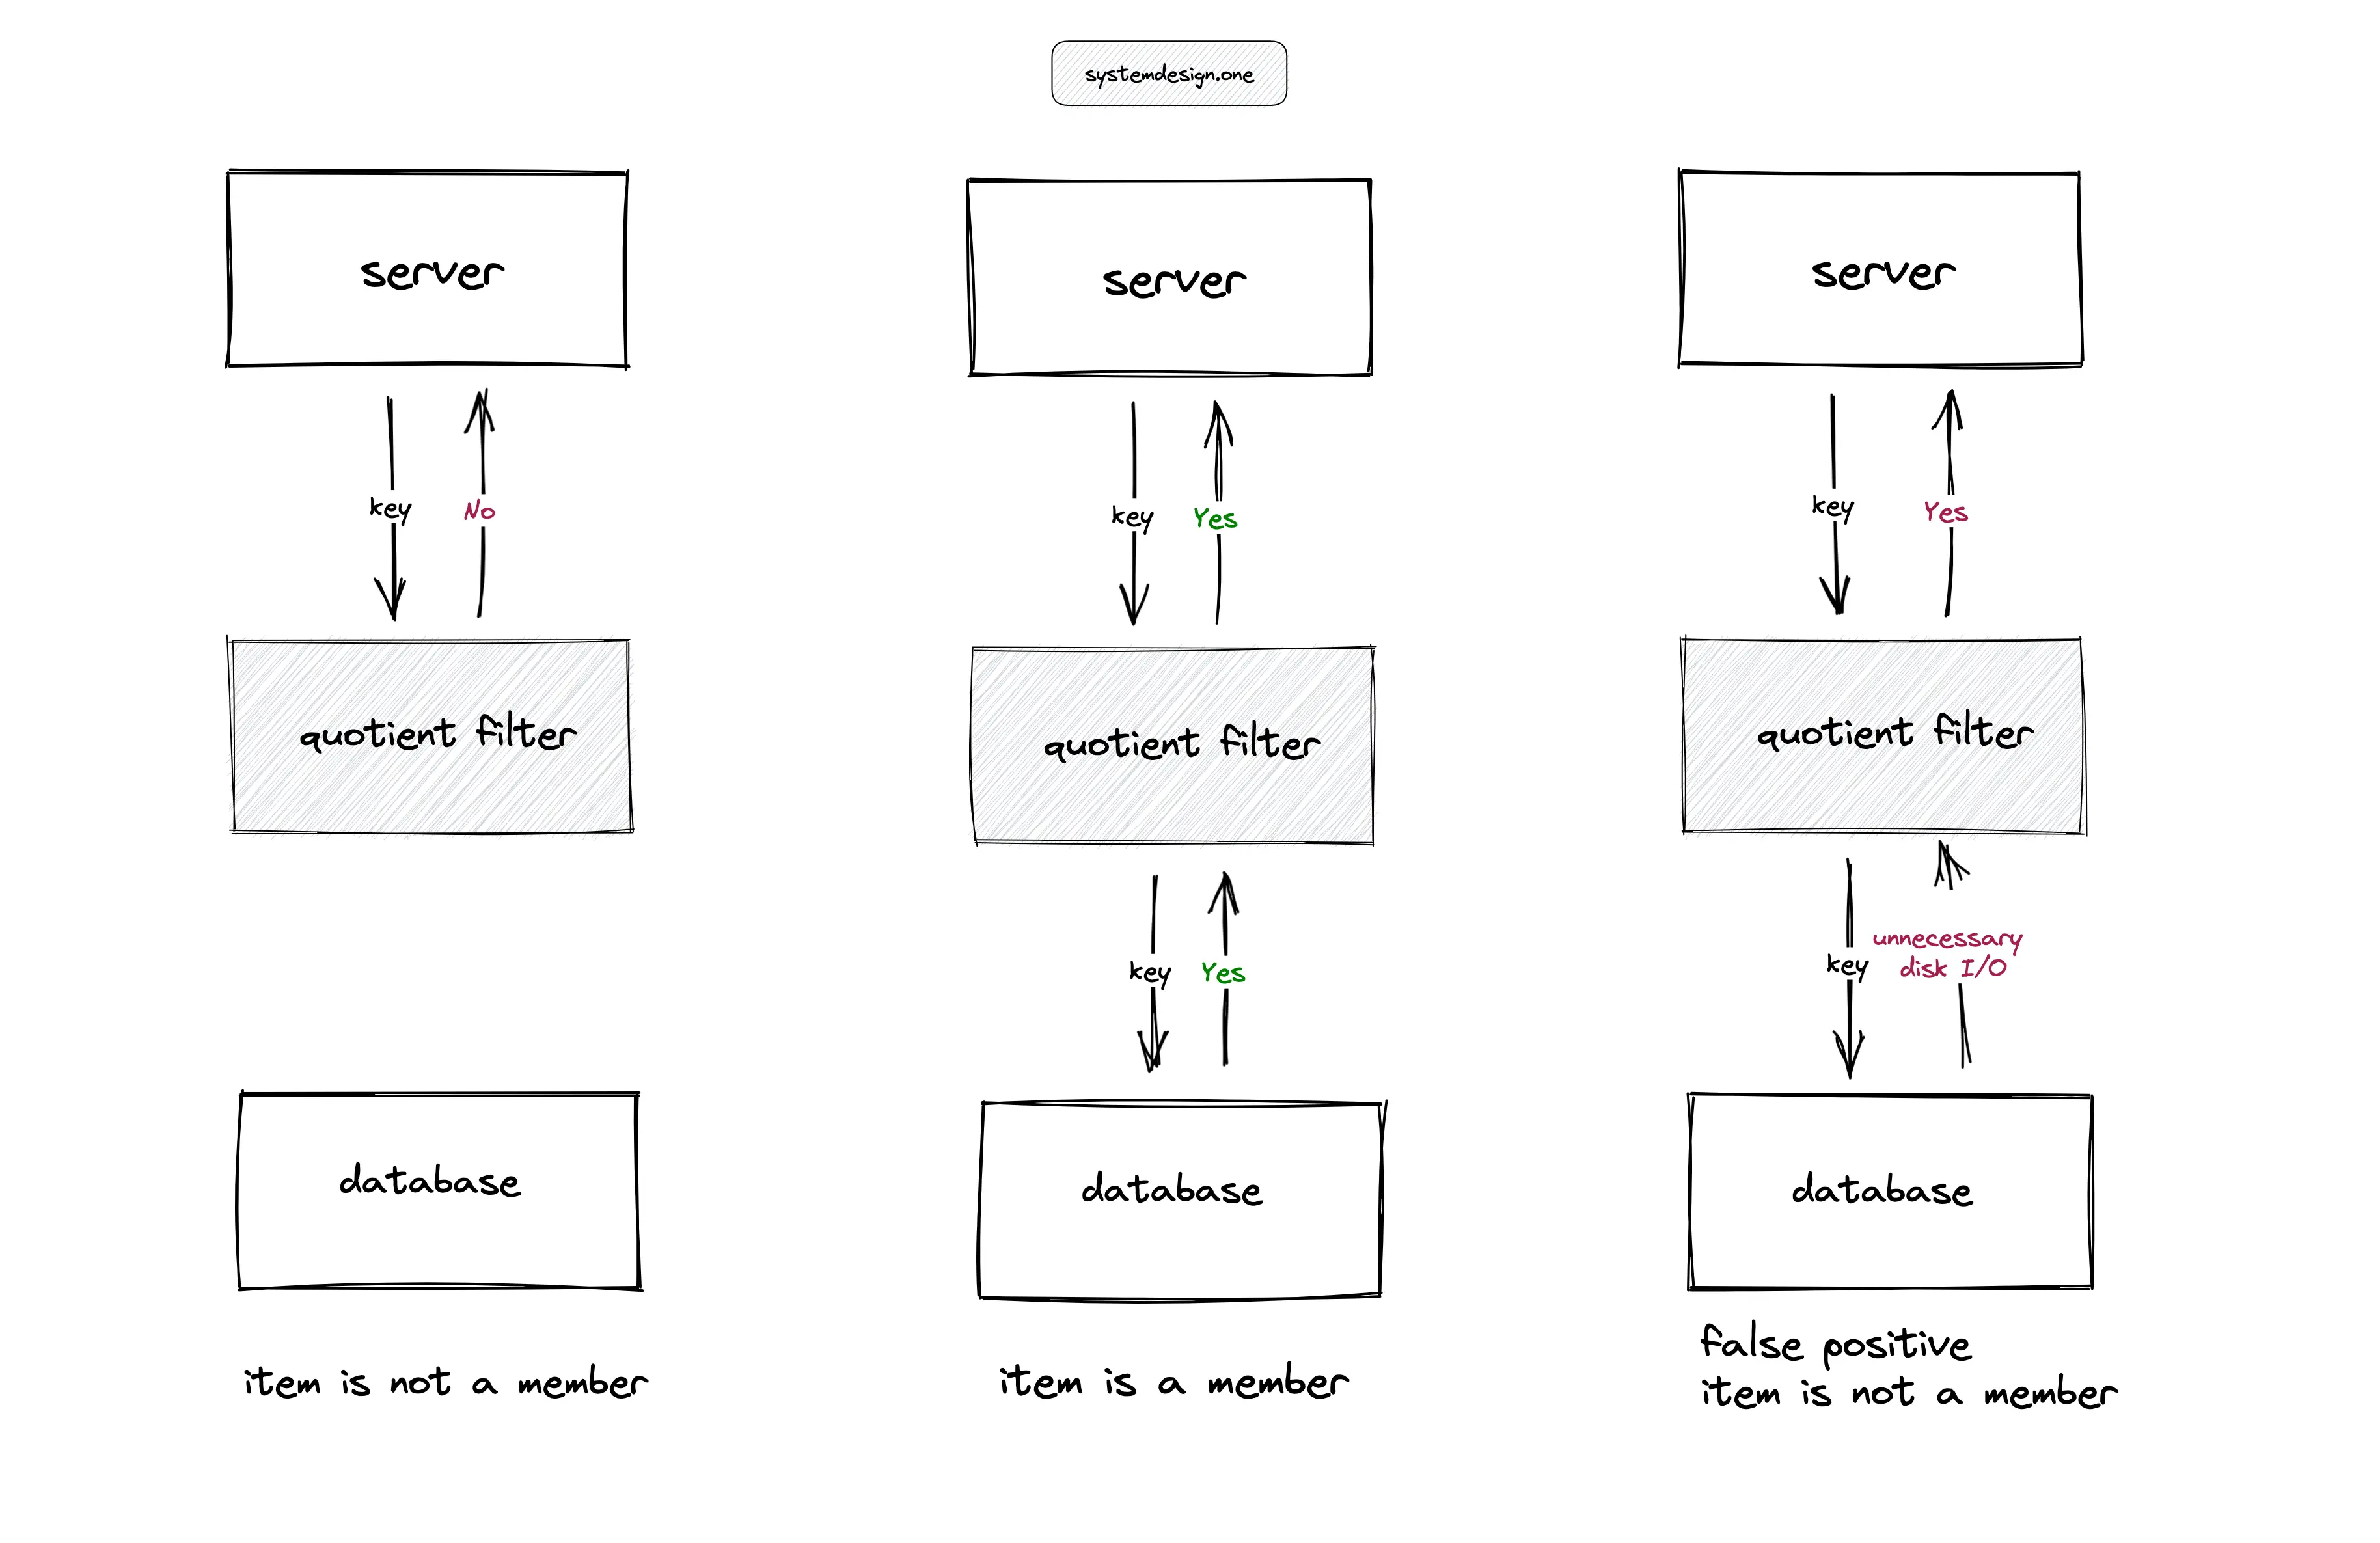
A quotient filter is a space-efficient probabilistic data structure that is used to test whether an item is a member of a set. The quotient filter will always say yes if an item is a set member. However, the quotient filter might still say yes although an item is not a member of the set (false positive). The quotient filter stores only a part of the item’s hash fingerprint along with additional metadata bits.
False Positive Etkisi
Şeklen şöyle. En sağda False Positive yüzünden gereksiz bir veri tabanı erişime yapılıyor


7 Haziran 2023 Çarşamba

Polyglot Persistence Nedir ?

Giriş
Açıklaması şöyle
Polyglot persistence is a term that refers to using multiple data storage technologies within a single system, in order to meet varying data storage needs.
İlk Nerede Ortaya Çıktı
Bu terim 2011 yılı civarında Martin Fowler Tarafından icat edilmiş. Orijinal yazı burada. 

Açıklaması şöyle. Çıkış noktası ise mikro servis mimarisine doğru gidişte her servisin kendi ihtiyacına göre verisini saklaması.
This concept of platform diversity was extended by Martin Fowler to databases in approx. 2011 when he coined (in what he calls his "bliki" - blog/wiki) the term polyglot persistence. His point was that different functionalities within a system can be best served by different databases
...
With the current move away from software monoliths and the trend for microservices where each area of a system is a different programme, possibly/probably living in a different container and/or server, this model is becoming more and more pertinent since the universal data interchange language of JSON and RESTful web services means that the impedance mismatch between different database systems is mitigated and not as important as it perhaps once was.

Google Cloud Datastream

Giriş
Açıklaması şöyle. CDC için sadece Oracle, MySQL, ve PostgreSQL veri tabanlarını destekler
If you use GCP and want to CDC, the limitation of Datastream is that it only supports a small number of databases at the moment.

6 Haziran 2023 Salı

Vector Database Nedir ?

Giriş
Açıklaması şöyle
A vector database is specifically engineered to efficiently deal with vector data. So, what’s vector data? It represents data points in multi-dimensional space, a mathematical approach to defining real-world information.

Consider this, you have an assortment of images. Each of these images can be represented as a vector in a high-dimensional space where each dimension relates to some feature of the image (like color, shape, or texture). By comparing these vectors, we can find similar images. Sounds neat, right?

This capability is pivotal because it enables similarity search — a type of search where you’re fishing for things that are similar, not necessarily exact replicas. This is a game-changer in many domains, like recommendation systems and machine learning.
Technologies behind vector databases
1. Indexing
Açıklaması şöyle
The foundation of vector databases lies in data indexing. Through techniques like inverted indexing, vector databases can efficiently conduct similarity searches by grouping and indexing vector features. Furthermore, vector quantization techniques aid in mapping high-dimensional vectors to lower-dimensional spaces, resulting in reduced storage and computational requirements. By leveraging indexing techniques, vector databases enable efficient searching of vectors using various operations such as vector addition, similarity calculation, and clustering analysis.
2. Vector Quantization
Açıklaması şöyle
Furthermore, vector quantization techniques aid in mapping high-dimensional vectors to lower-dimensional spaces, resulting in reduced storage and computational requirements. By leveraging indexing techniques, vector databases enable efficient searching of vectors using various operations such as vector addition, similarity calculation, and clustering analysis.
3. Storage
Açıklaması şöyle
Regarding the storage aspect of vector databases, it is noteworthy that indexing techniques take precedence over the choice of underlying storage.


Low Code Nedir ?

Giriş
Açıklaması şöyle. Yani eski sürükle bırak yöntemi gibi
Low code development refers to a visual development approach that empowers you to create applications with minimal manual coding. It provides a graphical interface and pre-built components that allow developers and non-technical users to rapidly build and deploy applications. This approach significantly reduces the time and effort required to create software solutions.

1 Haziran 2023 Perşembe

Staged Event-Driven Architecture - SEDA

Giriş
Açıklaması şöyle
In SEDA architecture, the flow of events through the system is divided into stages, and each stage has a bounded event queue. The processing of events is handled asynchronously and in a pipelined manner, allowing for better control over system resources and improved throughput.
Yani aslında bir çeşit pipeline gibi düşünülebilir. Her aşamayı (stage) farklı bir thread veya thread pool çalıştırır.